
AI Agent Memory: Conversation State, Retrieval and Stored Records
AI agent memory spans five systems: context window, transcript, retrieval store, profile, and business record. Learn their differences, stale-fact risks, and deletion boundaries.
AI agent memory spans five systems: context window, transcript, retrieval store, profile, and business record. Learn their differences, stale-fact risks, and deletion boundaries.
When a vendor says an agent remembers a customer, the claim can refer to at least five systems, each with its own lifetime, access controls, and failure modes. The practical question is never "does it have memory?" but "which memory, stored where, readable by whom, and deleted how?"
TL;DR
Large language models process a context window: the set of tokens supplied when the model samples a response. Anthropic engineers define context as "the set of tokens included when sampling from a large-language model." Everything an agent knows at a given moment (instructions, tool definitions, retrieved passages, and message history) occupies that window.
This window is a scarce resource. Anthropic documents context rot: as the token count grows, the model's ability to recall earlier information declines. Long conversations are handled with compaction, summarizing a conversation nearing the limit and starting a fresh window with the summary. Even within one session, "remembering" is lossy.
When the chat ends, the window disappears unless something writes a record elsewhere. One persistence pattern is structured note-taking, where the agent writes notes outside the window and pulls them back for later turns; Anthropic's context-engineering guide covers this as agentic memory. What persists is what you choose to store.
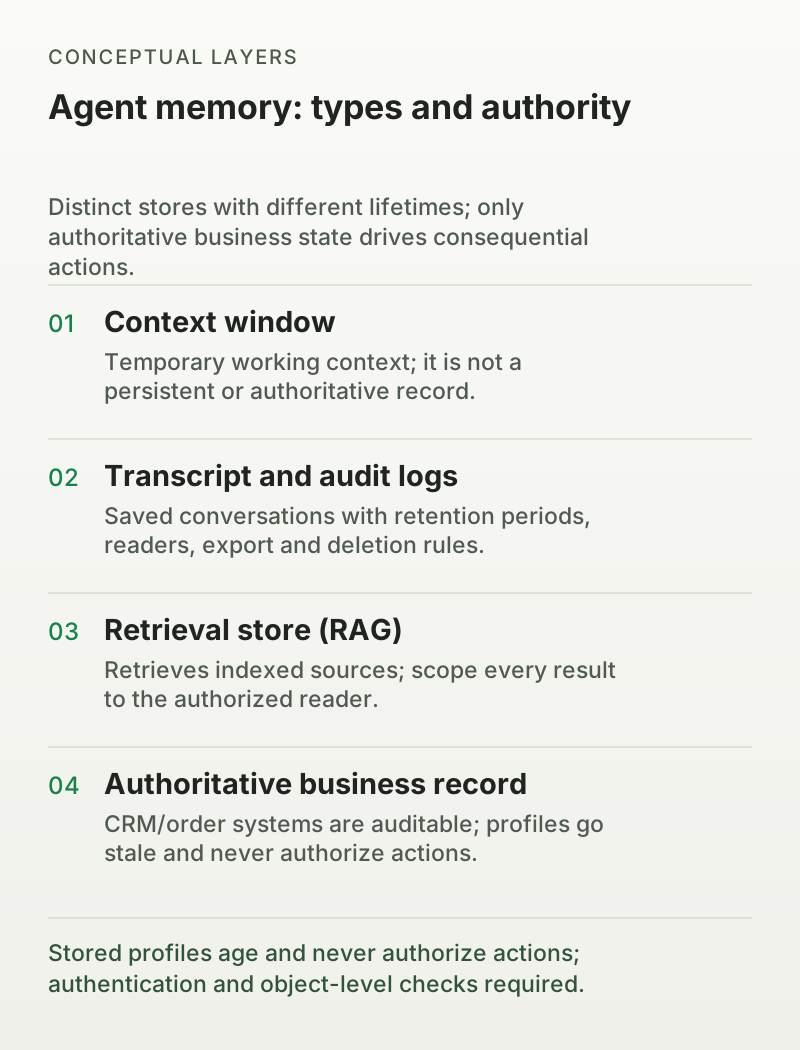
Persistent memory splits into four categories with different jobs. (See our AI agent entry for the surrounding term.)
Transcripts and audit logs. A saved conversation is memory. It has a retention period, readers, and export rules. If a customer asks you to delete their data, a transcript is often the hardest copy to find.
A retrieval store. Also called RAG or knowledge-base search, this is a vector index over documents the agent pulls into context at answer time. It answers "which document explains this?" It does not remember that a customer is on a premium plan. Retrieval is how the article is found; memory is how the customer is found. Mixing them is how a private detail ends up inside a prompt that never needed it. See our retrieval-augmented generation glossary.
A profile or preference store. The product keeps fields about the customer: name, plan, last order, maybe a summary a model wrote after a previous conversation. This is convenient and goes stale. A summary saying the customer threatened to cancel, written by a model on a bad day, will follow them until someone corrects it. Prefer typed fields from your own systems over free-form prose the model composed.
Authoritative business state. The CRM, order system, and help desk hold records the agent reads at answer time. This is memory you can audit because you already operate a process for correcting it. It is also the only store that should drive consequential actions like updating an address or issuing a refund.
Every piece of agent memory has a writer, a store, and a reader. Walk all three:
The most common failure is skipping the third step: reading a stored summary directly instead of verifying against the system of record.
Profile data is a snapshot, and snapshots age. A customer's payment plan changed yesterday: billing has the new value; the bot's profile may show the old one. If billing holds the truth, read billing. Do not keep a second copy of the same fact just because the demo called it memory. Every duplicate is a synchronization point, and every missed sync produces an answer that contradicts your own systems.
This applies squarely to model-written summaries: a summary is an inference at a moment in time, encoding what the model got wrong, and persists indefinitely unless you refresh it.
A customer writes: "For future orders, ship everything to my office address." The agent stores this preference in its profile. That is a reasonable use of profile memory.
Now suppose the same customer writes: "Change the address on order #4821 to my office." The stored preference says the customer prefers the office address. That is not authorization to modify order #4821. A typed email address or order number is a lookup key, not proof of identity. The agent must route the request through an authenticated customer session or a server-validated identity flow, then check object-level permissions before touching the order. If the customer is not signed in, a guest lookup can send a secure link to the stored contact address so the change happens outside the chat channel. The preference record is reference; the order system is authority.
If the agent treats the stored preference as permission to edit the order, two things go wrong: the customer is surprised by a change to a specific order, and any mechanism that lets stored text drive account changes becomes an attack surface. Security catalogs, most notably OWASP's LLM Top 10, list prompt injection, where stored or retrieved text steers model behavior, among the leading LLM application risks. The mitigation is architectural: action-bearing content lives in your authoritative systems behind your normal controls, not in free-text memory the agent trusts. For the defensive technique, see our prompt engineering glossary.
There is also a privacy angle: an office shipping address stored in a free-text profile is personal data. It persists, may be readable by support staff, and must be erasable on request.
A deletion request rarely targets one thing. If a customer asks you to remove their data, you must reach the transcript, the visible profile, and any vector index or derived summary, not only the record shown in the admin UI.
Ask these questions before you adopt an agent:
A plan line that says "custom retention" or "audit logs" tells you a capability exists, not what the default period is or how deletion propagates. The answer you want is the retention period and deletion path written into the contract. The NIST AI Risk Management Framework, a voluntary standard, frames this as a governance question: identify downstream harms, then design controls accordingly. Memory that cannot be audited or deleted is a liability you are choosing to carry.
For a fuller decision process, see our AI agent buying checklist.
Match the memory type to the decision. Most website agents need session memory and retrieval, nothing more. Profile memory earns its place when a returning customer would otherwise restate what you already store elsewhere, and even then, read the system of record for the final answer. Authoritative business state is where actions happen, so put guardrails there and keep stored text out of high-privilege paths. If you can answer "which store, who reads it, and how is it deleted" for each memory your agent uses, you have solved the real problem, and the marketing promise becomes something you can defend.
Is the context window a form of memory? Yes, but only as working state. It lasts for the session and degrades as it fills; Anthropic calls this "context rot." Unless something writes a record externally, it vanishes when the chat ends. Treat it as scratch space, not storage.
What is the difference between memory and retrieval? Retrieval (RAG) finds documents the agent uses to answer a question; it knows nothing about the individual customer. Memory refers to stored records about the customer or the conversation. Mix them and private details leak into prompts that never needed them.
Does a stored preference mean the agent is allowed to act on it? No. A stored preference is reference data, not authorization. In the shipping-address example, preferring an office address does not permit changing a specific order. Order changes require an authenticated customer session or server-validated identity, plus object-level authorization from the order system. An email address or order number alone is only a lookup key.
Why do model-written summaries go stale? A summary is an inference made at one moment, including whatever the model misinterpreted. It persists until someone corrects or refreshes it. Typed fields from your own systems update with the source; prose summaries do not. Prefer structured fields over narrative summaries for decision-relevant facts.
What should a deletion request cover? The transcript, the visible profile, and every derived copy such as summaries and vector-index entries. Ask how the vendor propagates a deletion across all of those; a checkbox in the admin UI may only touch the visible record.