
What Is Multimodal AI? Text, Images, Audio and Workflow Limits
Multimodal AI models process text, images, audio, and video. Understand the mechanics, the line between seeing and acting, and how to evaluate them for support workflows.
Multimodal AI models process text, images, audio, and video. Understand the mechanics, the line between seeing and acting, and how to evaluate them for support workflows.
A multimodal AI system processes more than one kind of input (text, images, audio, video, or documents) through the same model rather than through separate pipelines bolted together. Multimodal models are trained from the ground up to handle multiple modalities; Google's Gemini models, for example, accept images directly and can describe or classify them without separate ML models (Gemini API vision documentation). In customer service, research, and operations, this extends what an automated assistant can read: a photo of a damaged shipment, a screenshot of a billing error, a voicemail transcript, or a PDF label.
That capability is easy to oversell. Accepting an image is not the same as understanding your business rules, verifying an order, or taking an approved action. The practical question is always whether the file contains the fact the workflow needs, and what the model does when it does not.
Inside the model, each modality is converted into a shared representation the model can reason over. An image becomes visual tokens; audio can be transcribed or processed directly; a document becomes text plus layout signals. For developers, the integration point matters: you can pass an image inline in the request, reference it by URL, or upload it through a files API. Google's Gemini API includes all three methods (documentation). There are practical constraints: inline image data in Gemini requests is limited to 20 MB total including text and system instructions, so larger files need an upload endpoint.
This shared representation makes the model fluent, and that fluency is a risk: the same model that names a crack in a mug will happily guess at a policy outcome because it was asked for a helpful answer. The architecture explains the capability, not the judgment.
The model can also emit text, synthesized speech, or generated images, but a generated output is still just a signal until a tool carries it somewhere.
Context is also a finite resource. Anthropic describes "context rot": as tokens accumulate, the model's recall of earlier information degrades (effective context engineering). Long threads of screenshots and transcripts make this worse.
The most important distinction in multimodal work is between perception and action.
Perception is what the model does with the input: it reads pixels, hears audio, extracts text. That is genuinely useful. A text-only bot asks a customer to describe a cracked mug, then guesses. A multimodal bot can confirm the photo shows a crack.
Action requires a tool, a permission, and a rule. In Anthropic's framing, agents are LLMs using tools in a loop (building effective agents): the model proposes a tool call, the environment returns results, and the model decides the next step. Issuing a refund, updating a ticket, or checking an order requires a configured integration plus the underlying data. The presence of multimodal input does not grant those capabilities. You build them, scope them, and test them.
A successful API response is not a completed action. A 200 or 202 means the platform accepted the request; the refund or ticket change may still be pending or may have failed after acceptance. Read the operation state or the authoritative record before confirming anything, and design retries with idempotency so a timeout does not create duplicates.
In customer support, this split maps neatly: the picture answers "is there visible damage in the frame"; the help center answers "do we replace it." Keep those sources separate. A model that describes the crack should not invent the remedy.
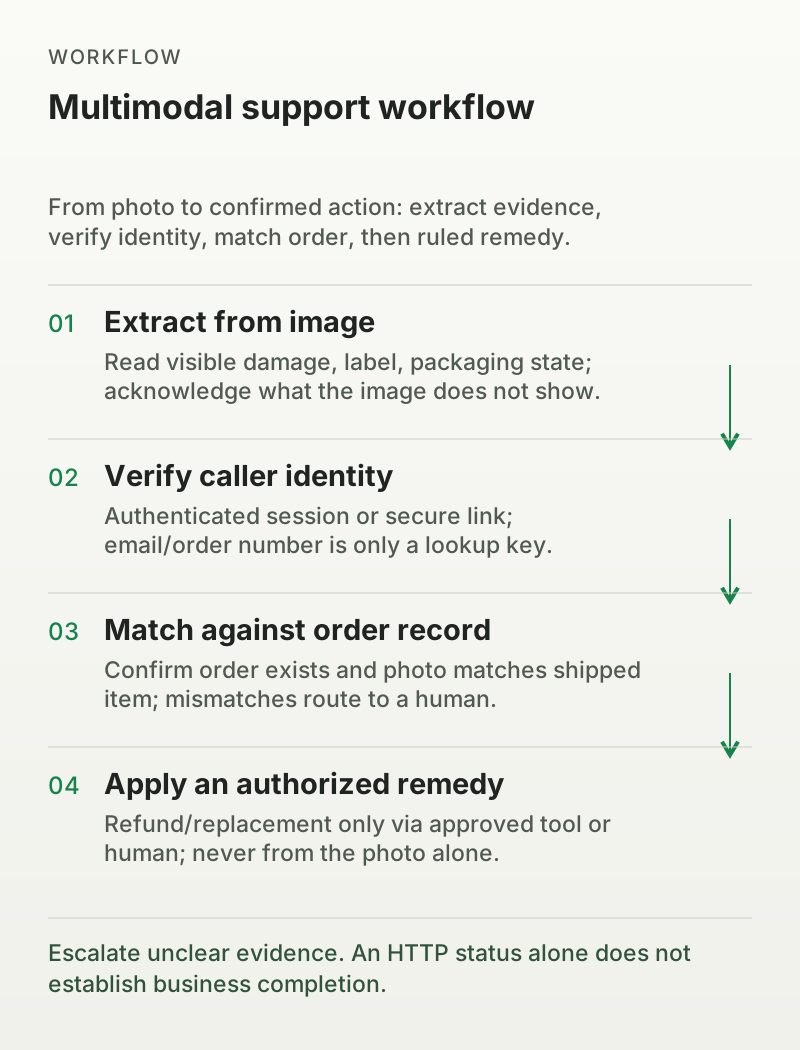
A customer writes "my package arrived crushed" and attaches a photo of the damaged box.
What the model can do with the image:
What it cannot do by itself:
So a useful workflow looks like this:
The same split governs the action. Treat a 200 or 202 response as accepted, not completed. Read back the authoritative order record or the job state to confirm the change landed, and check before retrying to avoid duplicate actions.
This is extraction versus trusted record. The photo is evidence; the order database is the record. A multimodal demo reel of clear, well-lit damage is not a test of this workflow.
The failure cases are ordinary customer reality:
The correct behavior is to fail and hand the thread to a person, not to improvise. A confident "you are on Pro" from a cropped header is worse than a question. Even a correct-looking header does not prove the person asking owns the account; identity requires an authenticated session or a secure verification flow. Test those images on purpose; teams routinely discover that happy-path demos hide the inputs that actually arrive.
Because a multimodal system is several capabilities in one product, evaluate each capability separately:
Missing information deserves its own test category. A model can produce a well-worded answer even when it cannot actually see the detail, because language generation fills gaps fluently. The safest design treats "I couldn't read that" as a legitimate, expected output, and routes accordingly, instead of asking the model to guess. This maps to a broader risk-management posture: frameworks like NIST's AI Risk Management Framework are voluntary but designed to weave trustworthiness into evaluation (NIST AI RMF). For a support workflow, that means measuring accuracy on the real distribution of attachments, not on curated examples. For security-specific failure modes, OWASP's Top 10 for LLM applications is a practical vulnerability checklist for systems that handle user-supplied files (OWASP GenAI Security Project).
Photos and audio often contain personal details: faces, addresses, account numbers, children's rooms, interior shots. Before deploying, ask where files go, how long they are kept, whether they are used to train models, and who can access them. In regulated settings, upload handling and retention need explicit review. Do not assume a demo or a dashboard implies a compliance assessment.
When evaluating a multimodal setup, get concrete answers:
For helpdesk usage, the cost meters around the thread still apply; the image changes what you are willing to let the agent close, not the meter itself. See the help desk comparison for how tickets are billed across platforms. Understanding how models represent and retrieve context also matters; the LLM glossary entry explains why a description can sound finished when the pixels were ambiguous, and the human-in-the-loop entry covers the review points that keep consequential actions safe.
Can multimodal AI issue refunds or take other actions from an image? Only if you wire the agent to a tool with permission, such as a refund API or ticket updater, and set the rule. The model proposes the action; the environment executes it. Verify the action completed against the authoritative record instead of assuming a successful API response means it happened. Never let a photo alone trigger a paid outcome; tie actions to verified records, authenticated identity, and human sign-off.
What file types do multimodal models accept? Commonly JPEG, PNG, GIF, and WebP for images, plus audio, video, and PDF depending on the provider. Check documented limits; inline data is often capped (for example, 20 MB total in Gemini API requests), with larger files requiring the files API.
How accurate are they at reading images? Accuracy depends on the modality, the task, and input quality. Strong models read clear, well-lit content well but degrade with blur, glare, cropping, and odd angles. Test on your real inputs; vendor demos are not benchmarks.
Do multimodal models keep the images they process? Depending on deployment. Some providers store uploads for processing and debugging; some delete promptly; some let you configure retention. Ask about storage location and whether data is used for training.
What should the bot do when an image is too blurry to read? It should say what it cannot read and route to a human or ask for a clearer shot, not infer missing details. A polished guess from a bad image is worse than a direct question.
Is multimodal AI automatically better than text-only for customer service? Not automatically. It helps when the needed fact lives in the image (damage, a screenshot, a label) and you have a safe workflow. If the decisive facts live in your order system, multimodal input mainly reduces typing, not judgment.
Multimodal input widens what an AI system can read, not what it can be trusted to do. Use it to extract, transcribe, and route. Anchor every consequential decision to a trusted record, test with poor-quality inputs, and keep a human or an explicitly scoped tool rule in charge of the action. That separation is the difference between a useful multimodal assistant and a confident liability.