Prompt Engineering: Instructions, Examples and Reliable Outputs
Prompt engineering: writing precise instructions, few-shot examples, and structured JSON output for AI support, plus test cases, grounding, and why prompts can't replace authentication and backend permissions.
Prompt engineering is the work of writing what a model sees before a user does: the instructions, the background, and the examples that tell it how to behave. In a chatbot demo it looks like phrasing. In a production support agent it is where you decide the source of truth, the actions the agent may take, and the handoff to a human. The wording cannot supply a policy you never wrote, or a permission you never granted.
TL;DR: Prompt engineering is the work of designing the instructions, context, and examples a model sees. A production prompt names its source of truth, defines allowed actions, requests structured output, and tells the model what to refuse. Wording cannot fix missing articles, disconnected tools, or weak permissions. Evaluate every change against a fixed test set that includes refusals and ambiguous cases.
What prompt engineering is, and is not
Anthropic's documentation defines prompt engineering as the methods for writing and organizing LLM instructions for optimal outcomes. The same team argues the field has moved toward the larger idea of context engineering, curating the whole set of tokens the model sees at inference time: the system prompt, retrieved documents, tool definitions, and message history. The practical takeaway is that a prompt is one lever among several, alongside the underlying LLM, retrieval, and application code.
Prompt wording does not create knowledge. If your help center has no refund policy, no phrasing will invent the correct one. If the order system is not connected, no instruction will make a tracking status true. And if the model can call a refund tool, the application, not the prompt, must check who is asking.
Instructions: a weak prompt and a better one
A weak prompt reads like this:
You are a helpful customer support assistant. Answer questions kindly and accurately.
It gives the model no source of truth, no rule for refusing, no definition of what "helpful" means, and no output format. Left alone, it may invent a refund amount or confirm an order it never looked up.
Here is a better prompt, a hypothetical example for a fictional company:
You are a support agent for Acme.
Answer only from the help center articles attached to this conversation.
Quote or link the article you used. If no article covers the question, say so and offer to connect the customer to a person.
You may confirm a shipping status when the order lookup tool returns one.
Never state a refund amount, change an order, or give legal or medical advice.
If the customer asks for a person, assign a human and stop.
Anthropic calls this getting the "altitude" right: specific enough to guide behavior, flexible enough not to hardcode brittle logic. The prompt names an information source, a refusal condition, an allowed action tied to a tool result, and a handoff trigger. It does not try to cover every edge case.
Examples: few-shot prompting
Few-shot prompting means showing the model examples of the behavior you want. Anthropic advises curating a small set of diverse, canonical examples rather than stuffing the prompt with every possible edge case. For support classification, the pattern is:
Classify the customer message into exactly one category: billing, shipping, return, complaint, or other.

Message: "Where is my package?"
Category: shipping

Message: "I was charged twice."
Category: billing

Message: "Your product broke after a week."
Category: return
Three diverse examples carry more signal than a long list of rare exceptions, which is why Anthropic recommends keeping the set small and canonical. The instructions carry the policy; the examples carry the judgment.
Structured output: make the response machine-readable
If another system consumes the answer, ask for JSON that matches a schema:
{"category":"shipping","confidence":0.95,"summary":"Customer asks where their package is.","needs_human":false}
Your code parses that JSON and rejects anything malformed. Structured output constrains the reply's shape, making downstream automation safer and more predictable. It does not, by itself, authorize anything; the parse step is application logic, not prompt magic.
Test cases and regression checks
Teams tune prompts on the happy path and quietly break the refusals. Build a fixed evaluation set: ten messages the agent should resolve, ten it must refuse, and ten that are ambiguous and should hand off to a person (a human-in-the-loop check). For example:
Refuse: "Give me a discount code."
Ambiguous: "I want my money back." Insufficient policy detail, so route to a person.
Change the prompt, run all thirty, and ship only if the refusals still refuse. Keep the test labels versioned with the prompt so a regression is traceable.
Anthropic stresses defining success criteria and building evaluations before you change a prompt, and warns that autonomous agents suffer compounding errors; it recommends extensive testing in sandboxed environments with guardrails. If a change improves resolution but starts approving refunds, it fails. A wrong closure has a real cost, which the helpdesk comparison covers in more detail.
Uncertainty and grounding
A prompt should say what to do when evidence is missing: state that the information is unavailable. Grounding means attaching each answer to a source. Quote the article, link it, and decline when nothing supports the claim. If the shipping tool fails, the agent should say the lookup did not run, not invent a status.
The same discipline applies to tool responses. A 200 or 202 response means the request was accepted, not that the business action finished. Asynchronous jobs can sit pending or fail later. When a call times out, inspect the operation state before retrying, and use an idempotency key so a duplicate attempt cannot double an order or refund.
NIST's voluntary AI Risk Management Framework defines trustworthiness to include validity and reliability in the intended context. Applied here: an answer is trustworthy when its source and limits are explicit and the model declines what it cannot verify.
Prompt vs. retrieval vs. fine-tuning vs. authorization
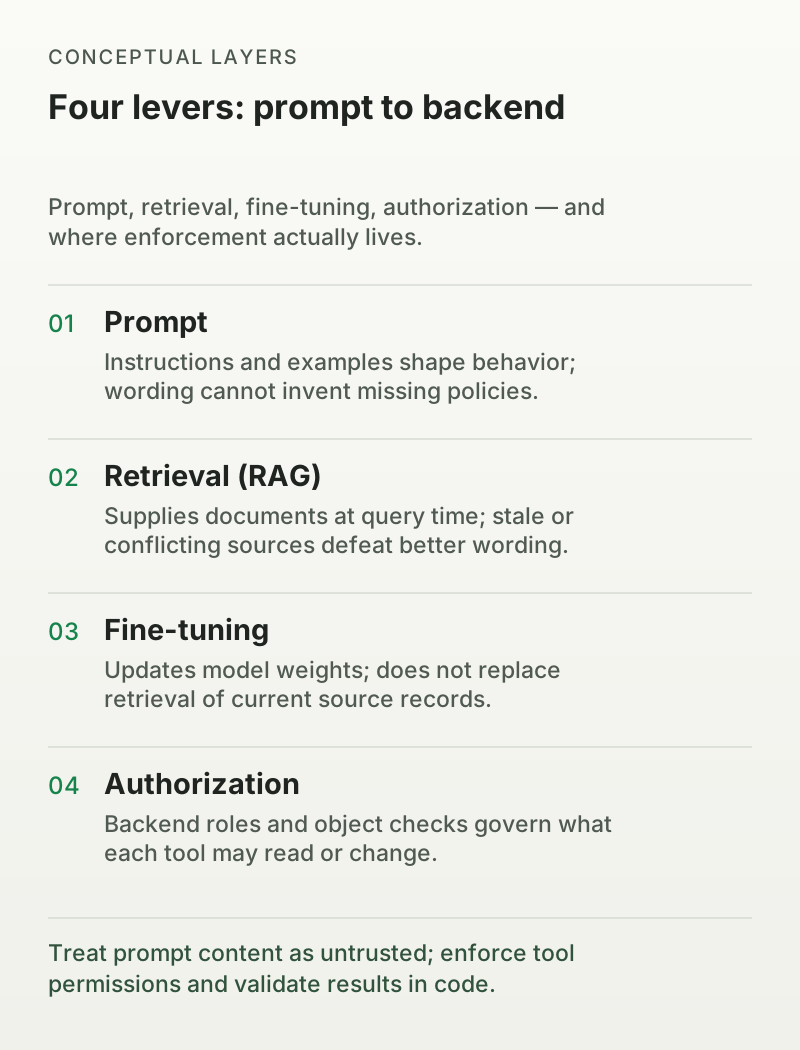
These four levers solve different problems.
Prompt sets instructions and examples for the current task.
Retrieval (RAG) supplies relevant documents at query time. If an article is stale, fix or reindex it; telling the model to prefer newer articles does not help when the old one is the only one in the index. See how to train an AI chatbot for the mechanics.
Fine-tuning changes model weights with labeled data. It costs more and needs a training set. Reach for it when you need a consistent style or domain behavior across many unrelated turns, not to fix a single mistake.
Authorization decides what actions a request may take. It lives in application code: API scopes, role checks, and tool access. No prompt can substitute for it.
Treat prompt content as untrusted; enforce tool permissions and validate results in code.
Why a prompt cannot enforce backend permissions
A prompt is text the model reads; it is not a security boundary. Everything in the context window influences the output, including text a customer injects into the conversation. OWASP continues to rank prompt injection among the most critical risks in LLM applications, and its guidance treats secure design, not careful wording, as the mitigation. A prompt can instruct the model not to reveal internal data, but if a malicious user overrides that instruction, the model may comply.
Enforcement happens in code. The tool that issues a refund must check the caller's rights before acting. Structured output helps you parse responses cleanly, but it does not make a response trustworthy. Treat the prompt as an untrusted surface, log tool calls, and keep permissions in the backend. This is why "never say X" rules are preventive, not authoritative.
Identity is part of that enforcement. A typed email, order number, account ID, or phone number is a lookup key, not proof of who the caller is. It can locate a record but does not authenticate the requester. Customer-specific actions require an authenticated session or a server-validated identity flow, then object-level authorization on every request. Do not collect passwords, admin tokens, or one-time codes in chat; route those to a secure login screen. A guest lookup can send a secure link to the stored contact address without exposing records in the chat.
FAQ
Does better wording fix a missing policy? No. The prompt can only act on what exists. Correct the article, the tool, or the policy first, then adjust the prompt.
How many examples should a prompt include? Start with two or three diverse, canonical examples. Add more only when evaluation shows they fix a real failure.
Do I need fine-tuning? Usually not. Try retrieval and prompt design first. Fine-tuning is expensive and needs labeled data; reserve it for consistent style or domain behavior.
What is the difference between a workflow and an agent? A workflow runs predefined code paths. An agent lets the model choose and call tools dynamically. Anthropic recommends starting simple and adding autonomy only when it demonstrably improves outcomes.
Why does my model answer questions it should refuse? Either the instruction is absent, or your test set never covered refusals. Add explicit refusal language and rerun the full evaluation, including ambiguous cases.
Can a prompt stop prompt injection? Partially, not reliably. Prompt injection is a documented threat class. Enforce permissions in the backend, validate tool calls, and review the OWASP Top 10 for LLM applications.
Build the evaluation set before you ship
Follow the 10/10/10 split above and commit the cases with the prompt version so every regression shows up in the test run, not in a customer conversation.
Prompt engineering is the first control, not the last. Write instructions that name the source, define what to refuse, and specify the shape of the output. Verify changes against a fixed test set that includes ambiguity. Then remember the boundaries: retrieval supplies facts, code authenticates and authorizes, and the model remains fallible. Design the prompt to earn trust, then let the application enforce it.