
How to Build an AI Chatbot: Retrieval, Tools and Production Checks
When a hosted chatbot can't reach a private system, build one. A practical guide to request contracts, retrieval, citations, identity, tool allowlists, and production checks.
When a hosted chatbot can't reach a private system, build one. A practical guide to request contracts, retrieval, citations, identity, tool allowlists, and production checks.
The decision to build a chatbot is usually made before anyone writes code. A hosted agent trained on your help center will answer most of the same questions a custom stack answers, with retrieval, guardrails, and handoff already handled. You should build your own only when the job cannot be bought: the bot must act in a system a host cannot reach, the data must stay inside a boundary a host's plan does not meet, the conversation happens inside your product, or it must use your own identity system. Our AI chatbot buying checklist covers the host-side choices in more depth.
That said, building mostly means assembling proven parts, not doing research. The model is the smallest part of the project. Retrieval, the contract you give the model, the tools it may call, the log of what it did, and the switch that turns those tools off are the actual product. This guide walks through each decision with a concrete request contract, provider-neutral pseudocode, and success criteria you can verify.
Most teams should start hosted. Current published prices from official pricing pages, reviewed 26 October 2026: Chatbase Hobby costs $32/month billed yearly with 700 message credits; YourGPT Essential costs $39/month billed annually with 10 million AI credits; Tidio Starter is $24.17/month annually with 100 billable conversations and a one-time 50 Lyro AI conversation allowance. If a queue already exists, Zendesk Support Team starts at $19/agent/month annually, Freshdesk Growth at $19/agent/month annually with the first 500 Freddy AI sessions, and Intercom Essential shows a promotional $19/seat/month against a $29 list price. Gorgias publishes a Helpdesk + AI Agent bundle where AI sits on every plan and you pay only when it resolves a conversation; exact per-ticket rates come from a quote because pricing scales with ticket volume, not seats. These are vendor-documented prices, not independent performance claims.
One detail matters before you compare plans: credit units are not interchangeable. YourGPT's docs list model-specific consumption rates, such as GPT-4o at 2x credits and tier-3 efficient models at 0.5x, so your usable capacity depends on which model you run. Chatbase's message credits are a separate billing unit, and a credit is not defined as one fixed conversation. Read each vendor's usage definition before sizing a plan.
Hosted agents already solve the hard coordination problems. They ingest your site or documents, chunk and embed them, generate answers with citations, and hand off to a human. Chatbase, for example, documents Shopify, Slack, WhatsApp, Messenger, and Instagram channels on its Hobby plan. YourGPT documents training from URLs, sitemaps, help centers, Notion, YouTube, and uploaded PDF, CSV, TXT, DOCX, PPTX, or MD files, with a manual dashboard ReIndex button or a configurable reindexing schedule. If you already run a helpdesk, Fin can sit on top of it at $0.99 per outcome with a 50-outcome monthly minimum and no seat costs, per Fin's pricing page.
What hosted platforms still constrain is scope. A widget runs in your help center or on your site, not deep inside your application. It talks to the integrations the vendor built. It treats the visitor as an anonymous web user. And the data you upload lives on the vendor's infrastructure, governed by its plan and compliance terms.
If none of these apply, stop here. Train the hosted agent on your best articles, test, and ship.
Before you pick a model, define what one exchange looks like. A contract is a JSON shape both sides agree on. Without it, the model's output is a string you cannot reliably parse, cite, or audit.
Here is a minimal request and expected response:
Request body (the application session carries authentication separately):
{
  "conversation_id": "conv_77aa",
  "message": "Cancel my order #48291",
  "request_id": "req_1042"
}
Expected response body while the cancellation is pending:
{
  "reply": "I found order 48291 and submitted the cancellation. I will confirm once the order service reports it.",
  "citations": [
    {
      "source": "order-service",
      "reference": "ORD-48291"
    }
  ],
  "actions": [
    {
      "tool": "cancel_order",
      "status": "submitted",
      "idempotency_key": "user_17::req_1042::cancel_order::ORD-48291",
      "target_id": "ORD-48291"
    }
  ]
}
Every field is deliberate. conversation_id lets you deduplicate and trace. access_token is a short-lived credential your backend issued; the server resolves it to a principal and applies object-level authorization. The client never supplies a user id or role as proof of anything. citations is the evidence trail. actions is the machine-readable record of what the bot attempted; note the status says submitted, not confirmed, because the order service must verify the change before the bot says it happened. If a response contains neither a citation nor a confirmed action for a factual or operational question, treat it as incomplete.
Define the refusal cases in the contract too. The bot should return an explicit needs_human flag rather than improvising when it lacks authority or information.
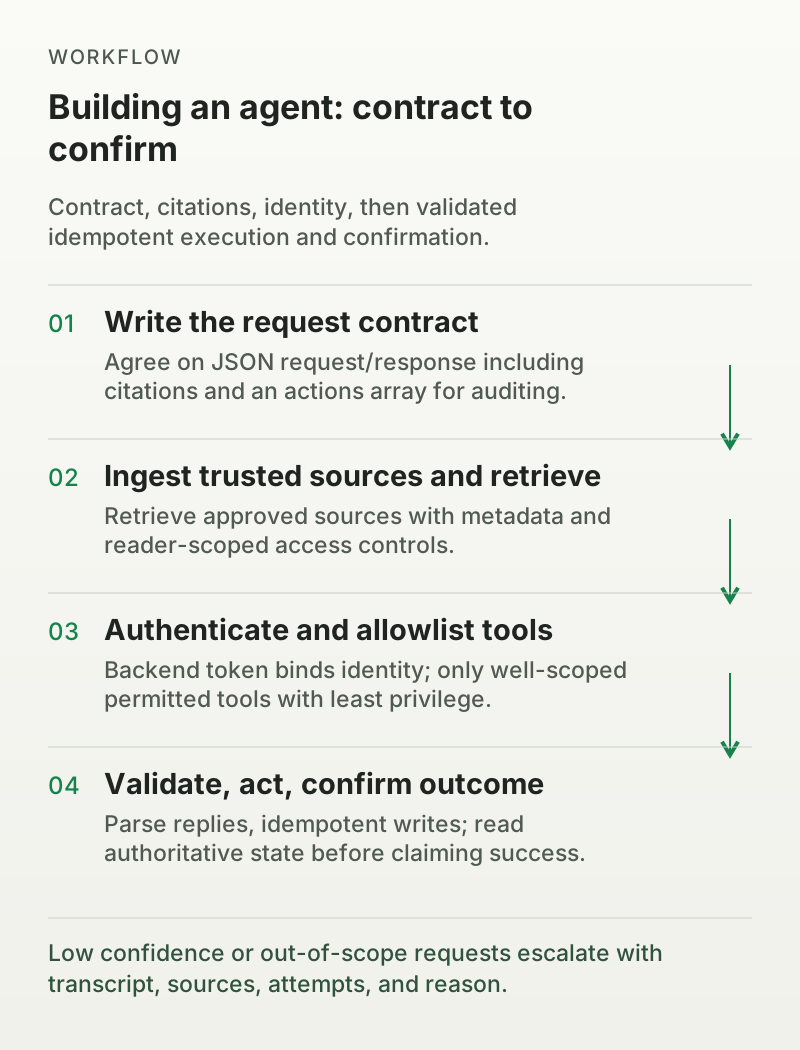
Retrieval quality starts upstream. If you feed the index stale policy pages and a customer forum, the bot will confidently repeat both. Keep a short list of canonical sources: your help center, your product documentation, your policy documents, and the tables your tools read from. Remove duplicates and resolve contradictions before indexing. How to train an AI chatbot covers source curation in more detail.
When you use a managed platform, reindexing is often manual or scheduled. YourGPT documents a manual ReIndex button in the dashboard plus a configurable reindexing schedule. Whatever you build, put the refresh on a calendar or a webhook tied to content changes, and assign an owner.
Chunking is where retrieval quality is decided. Split documents into passages that stand alone, typically a few hundred to about a thousand tokens, with modest overlap so a boundary sentence does not lose its subject. Attach metadata: source URL, document version, publish date, and a stable ID. Embed the chunks, then store them in a vector index.
At query time, retrieve the top-k chunks by similarity, but do not trust similarity alone. Filter by metadata when you can, for example only current policy versions, and pass the retrieved chunks plus their sources into the prompt. If your domain has strong structure (order numbers, SKUs, dates), add a keyword or structured lookup ahead of semantic search; retrieval on identifiers via embedding alone is unreliable. The RAG glossary explains the mechanism behind this step.
An answer that cannot name its source is a hallucination waiting to be noticed. Instruct the model to wrap each factual claim in a citation to a retrieved chunk, and render the source in the UI. When the answer relies on a live database record, cite the service and the record ID, as in the example above. This is what separates "looks plausible" from "can be audited," and it is the mechanism that lets you improve the bot later by fixing the offending source.
A citation payload should be machine-readable, not just a footnote in the reply text:
{
  "fact": "Returns are accepted within 30 days of delivery.",
  "citation": {
    "source": "help-center",
    "reference": "returns-policy-v12",
    "fetched_at": "2026-10-26T09:14:00Z"
  }
}
If your collection stores chunk IDs linked to documents, reference the chunk ID and the document version so you can locate exactly what the model saw. A citation to a live service record should include the service name and the record ID (for example, order-service and ORD-48291). Store the fetched timestamp so an audit can tell whether the answer predates a policy change.
Anonymous web visitors get public information. Logged-in users get their own account data. That separation is an authorization rule, not a prompt instruction. Your backend issues a signed token to the front end, and the bot's API validates that token and attaches the caller's identity to every request. Do not accept a user-supplied user id as proof of anything.
A typed email, order number, account ID, or phone number is a lookup key, not proof of identity. Matching text to a database row does not authenticate anyone. Customer-specific records and actions require an authenticated customer session or a server-validated identity flow, followed by object-level authorization on every request. If the customer is not logged in, offer a secure login or verification screen instead of taking credentials in chat. Never collect passwords, admin tokens, or one-time codes inside the conversation. For a guest lookup, you can send a secure link to the stored contact address and let the customer verify there, without exposing records in chat. The bot's tool calls must reference the authenticated principal so the order service checks that the order belongs to that user. This is non-negotiable whenever the bot can read or write private data.
A bot that can call any endpoint will, eventually, call the wrong one under the right prompt. Keep a hard list of permitted tools and the specific parameters each accepts. Grant the least privilege. Separate read actions from write actions, and require confirmation before a write. Prefer a small set of well-scoped tools over a generic "run SQL" or "call arbitrary API" tool. Log every invocation with the caller identity, request ID, and result so you can replay an incident.
All credentials stay server-side, and ownership plus permissions precede any data access or action. If your product runs on Shopify, note the 1 January 2026 change: new custom apps can no longer be created in the Shopify admin. Build new apps through the Dev Dashboard or Shopify CLI and follow the current authentication docs; older admin-generated token tutorials are legacy only, and native app installs are a separate path. Every code sample in this guide is provider-neutral pseudocode, not a vendor API reference.
When you evaluate a hosted platform, check that its action surface is similarly constrained. YourGPT's Shopify actions (product search, product details, add to cart, view cart) are documented to require Agent Mode to be enabled, and enabling them does not by itself grant Shopify Admin API permissions. Gorgias charges a helpdesk ticket fee for any replied ticket and an additional automation fee only when AI fully resolves a ticket without handing it to a human, per its current billing docs; older contract terms may differ, and current per-ticket rates require a quote. The agent vs automation guide helps with this distinction.
Model output is untrusted input. Parse the response, validate it against the contract schema, and reject malformed replies. Then handle failures deliberately:
idempotency_key in the contract ensures that retrying "cancel_order" cannot double-cancel or issue two refunds. Generate the key once per logical action and reuse it on retries.A successful API response is not a completed business action. A 200 or 202 only means the request was accepted; the write may still be pending or failed. After a tool call, read the operation state or the authoritative record to confirm the outcome. On a timeout, inspect the operation's state before retrying instead of blindly replaying. Customer confirmation and backend success are distinct: say "we have submitted your cancellation" until the order service confirms it.
A minimal orchestration skeleton in provider-neutral pseudocode:
def handle_message(request, session):
    user = authenticate(session)                   # trusted session transport
    if not user:
        return error("unauthenticated")

    chunks = retrieve(user, request["message"])      # step 3
    reply = model_response({
        "contract": CONTRACT,
        "user": user,
        "message": request["message"],
        "chunks": chunks,
    })

    if not validate_against_contract(reply):         # step 7
        raise MalformedReply(reply)

    for action in reply["actions"]:
        require_allowed_tool(action["tool"])
        authorize_target(user, action)              # role + object-level access
        validate_tool_arguments(action)
        key = operation_key(
            user.id, request["request_id"], action["tool"], action["target_id"]
        )
        operation = submit_tool(action, idempotency_key=key)
        state = read_authoritative_state(operation)
        record_action_state(reply, action, state)   # pending, failed, or confirmed

    if reply.get("needs_human"):
        escalate(user, reply)                        # step 8

    return reply
The exact names will differ by framework. The structure is what carries the guarantees: authenticate, retrieve, generate under a contract, validate, execute with idempotency, verify the outcome, and escalate when needed.
Every bot needs a limit it will not cross. Define escalation triggers explicitly: low retrieval confidence, a request outside the allowed tool set, a user asking for a human, or a sensitive operation your policy reserves for people. On escalation, hand over the conversation history plus the latest retrieved context and the failed attempt, so the human does not re-ask the customer. Escalation should be a designed pause, not a crash. See the human-in-the-loop glossary entry for the supporting concept.
The escalation record should contain everything the human needs to act without repeating the customer:
Pass this bundle as a structured payload, not as a prose summary. A human who has to ask "which order?" has already lost the benefit of the escalation.
Build a test set from real traffic. Pull fifty or a hundred messages your customers actually sent, and split them into groups: questions the bot must answer accurately, refusals it must not answer, and operational requests whose outcome you can verify end to end. Run these through the pipeline before every deploy. Add adversarial examples: conflicting policies, out-of-scope requests, and attempts to trick the model into revealing tools.
Track at least these numbers: retrieval hit rate (did the right chunk surface?), answer accuracy on a reviewed sample, refusal correctness, tool success rate, and average time to human pickup on escalations. Review transcripts weekly. Fix the source or the tool when a pattern of mistakes appears, rather than tuning prompts blindly.
| Check | Pass condition |
|---|---|
Contract | Every reply parses against the schema for a reviewed sample |
Retrieval | Top-k results contain the relevant passage for 90%+ of test questions |
Citations | Each factual claim points to a source or live record |
Identity | Private-data reads bind to the authenticated user |
Tools | Only allowlisted calls fire; every write is logged and idempotent |
Escalation | Trigger rates match expectations; handoff preserves full context |
These targets are illustrative; calibrate them with your own baseline before treating them as commitments.
When should I not build a custom chatbot? When a hosted agent trained on your help center covers your questions and your defined scope. The prices listed earlier in this guide make the hosted baseline inexpensive compared with running your own stack.
What is the hardest part of building a chatbot? Keeping answers grounded. Retrieval quality, source freshness, and citations need continuous care; a confident answer can still be wrong if the source was stale, conflicting, or not retrieved. Budget for ongoing source review, not just launch day.
Can the bot verify a customer by their email address? No. An email address or order number is a lookup key, not proof of identity. Use your own login or a server-validated verification flow, and never collect passwords or one-time codes in chat. For a guest lookup, send a secure link to the stored contact address.
Do I need a vector database? Not necessarily. Small corpora work with simple search or a curated FAQ index. When documents grow or phrasing varies, a vector index helps. Start minimal, then scale when retrieval quality becomes the bottleneck.
Why is idempotency important? Network and model retries can double-apply an action. An idempotency key lets the backend recognize a repeated "cancel order" request and return the prior result instead of cancelling twice. Without it, a flaky connection can turn one refund into two.
Can I put a custom bot inside my product? Yes, and it is one of the strongest reasons to build. In-product assistants need your identity system, UI context, and permission model, things a standalone widget lacks. Apply the same contract, retrieval, and testing rigor.
Is a fine-tuned model better than retrieval? Fine-tuning teaches style and format, not reliable facts, and it slows updates. Build retrieval with a strong base model first; fine-tune later only for a narrow, stable formatting task.
Buying a hosted agent is usually the correct decision, and the prices above make that easy to see. Build when a private action, a data boundary, an in-product channel, or your own identity system forces it. Then the engineering is mostly discipline: define the contract, curate sources, cite everything, authenticate the user, allowlist tools, make writes idempotent, and escalate deliberately. The model is a component. The production checks are the product.